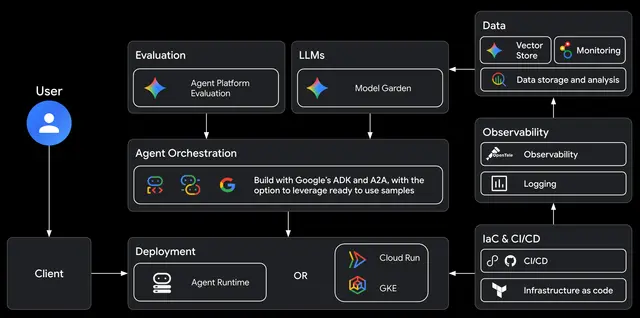
Google Agents CLI Eval
Should be used when the user wants to "run an evaluation", "evaluate my agent"...
Install
npx skills add google/agents-cli --skill google-agents-cli-eval -g -a claude-code -y- Repository
- google/agents-cli6.3k
- Category
- Data and ML
- Updated
- 8d ago
- License
- Apache-2.0
- Context cost
- Mediumabout 3,000 tokens
- Runs scripts
- No, instructions only
What it does
This skill should be used when the user wants to "run an evaluation", "evaluate my agent", "evaluate my ADK agent", "write an eval dataset", "analyze eval failures", "compare eval results", "optimize agent", or needs guidance on the Gemini platform eval methodology and the Quality Flywheel. Covers eval metrics, dataset schema, LLM-as-judge scoring, and common failure causes. Applies to any agents-cli project, whatever framework the agent is written in. Do NOT use for agent API code patterns (ADK: use google-agents-cli-adk-code), deployment (use google-agents-cli-deploy), or project scaffolding (use google-agents-cli-scaffold).
Agent Evaluation Guide
Requires:
agents-cli(uv tool install google-agents-cli), install uv first if needed.
Scaffolded project? If you used
/google-agents-cli-scaffold, dataset and a custom metric are already scaffolded intests/eval/(Python projects) oreval/(Go projects). For simplicity, this skill and its references use the Python directory layout; adjust accordingly if you've scaffolded a Go agent. You already haveagents-cli eval run(chainsgenerate+grade),tests/eval/datasets/, andtests/eval/eval_config.yaml. Start with executingeval runand iterate from there.
Reference Files
| File | Contents |
|---|---|
references/dataset_schema.md | Canonical EvaluationDataset schema, all field types, JSON examples for single-turn / multi-turn / multi-agent, common mistakes |
references/metrics-guide.md | Complete metrics reference, all built-in metrics, match types, custom metrics, judge model config |
references/user-simulation.md | Dynamic conversation testing, eval dataset synthesize flags, what scenarios are, compatible metrics |
references/builtin-tools-eval.md | google_search and model-internal tools, trajectory behavior, metric compatibility |
references/advanced-commands.md | Opt-in commands: eval analyze, eval optimize, eval submit / eval results |
references/multimodal-eval.md | Multimodal inputs, eval dataset schema, built-in metric limitations, custom evaluator pattern |
references/live-eval.md | Live and voice agents, --mode adk_live, what gets graded, user-only turn authoring, the Live-model and region traps |



