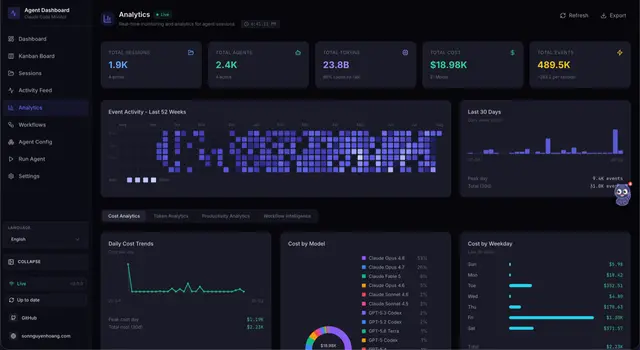
Benchmark
Benchmark one session (or a small recent set) against the rolling average using Agent...
Install
npx skills add hoangsonww/Claude-Code-Agent-Monitor --skill benchmark -g -a claude-code -y- Repository
- hoangsonww/Claude-Code-Agent-Monitor1.1k
- Category
- AI and agents
- Updated
- 5d ago
- License
- MIT
- Context cost
- Lightabout 732 tokens
- Runs scripts
- No, instructions only
What it does
Benchmark one session (or a small recent set) against the rolling average using Agent Monitor data, cost, total tokens, tool count, and workflow complexity score, and report where each metric lands as a percentile of the population. Tells you whether a session was normal, cheap, or an outlier. Use when judging whether a session was typical or out of band.
Benchmark
Score a session against the rolling population average and report its percentile on cost, tokens, tool count, and complexity using Agent Monitor data.
Input
The user provides: $ARGUMENTS
This may be:
- A single session ID, benchmark that session
- "latest", benchmark the most recent session
- "latest N", benchmark the N most recent sessions, each vs the average
- empty, benchmark the most recent session (default)
Data Sources
| Endpoint | Returns |
|---|---|
GET /api/sessions?limit=N | Population of sessions with cost, model, started_at, metadata (turn_count, total_turn_duration_ms), builds the rolling baseline |
GET /api/pricing/cost/{sessionId} | { total_cost, breakdown:[{ input_tokens, output_tokens, cache_read_tokens, cache_write_tokens, cost }] }, the target session's cost and tokens |
GET /api/workflows/{sessionId} | complexity (score), stats (tool/event counts), toolFlow (distinct tools used), the target session's tool count and complexity |
GET /api/analytics | avg_events_per_session, tool_usage, daily_sessions, corroborates population-level averages |
Report Sections
1. Build the Baseline
Fetch the population with GET /api/sessions?limit=200 (the rolling set). For each
session gather cost (GET /api/pricing/cost/{id} or the list cost field), total
tokens (sum of the 4 token types from the pricing breakdown), tool count and
complexity (GET /api/workflows/{id}). Compute mean, median, and standard
deviation for each metric across the population.
2. Measure the Target
For the requested session, pull the same four metrics:
- Cost,
total_costfromGET /api/pricing/cost/{id}. - Total tokens,
input + output + cache_read + cache_writesummed from the breakdown. - Tool count, distinct/total tools from
GET /api/workflows/{id}stats/toolFlow. - Complexity score,
complexity.scorefromGET /api/workflows/{id}.




