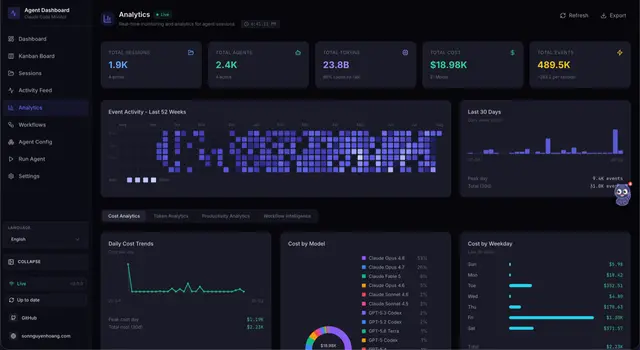
Productivity Score
Calculate a productivity score using actual Agent Monitor metrics, session completion...
Install
npx skills add hoangsonww/Claude-Code-Agent-Monitor --skill productivity-score -g -a claude-code -y- Repository
- hoangsonww/Claude-Code-Agent-Monitor1.1k
- Category
- AI and agents
- Updated
- 5d ago
- License
- MIT
- Context cost
- Lightabout 804 tokens
- Runs scripts
- No, instructions only
What it does
Calculate a productivity score using actual Agent Monitor metrics, session completion rates, cache efficiency (cache_read vs input), compaction pressure (baseline tokens), turn velocity (turn_count / total_turn_duration_ms), tool success ratio (PreToolUse vs PostToolUse), and the workflow intelligence API's complexity and effectiveness scores.
Productivity Score
Calculate a productivity scorecard from the Agent Monitor's real data.
Input
The user provides: $ARGUMENTS
Options: "today", "this week", "last 30 days", a session ID, or "compare" for period comparison.
Data Sources
| Endpoint | Returns |
|---|---|
GET /api/analytics | Token totals (total_input, total_output, total_cache_read, total_cache_write, baselines pre-summed), tool_usage top 20, daily_events/sessions, event_types, sessions_by_status, agents_by_status, avg_events_per_session, total_subagents |
GET /api/sessions?limit=100 | Sessions with metadata JSON: thinking_blocks, turn_count, total_turn_duration_ms, usage_extras (service_tier, speed, inference_geo) |
GET /api/pricing/cost | Total cost with per-model breakdown |
GET /api/workflows/{sessionId} | 11 workflow datasets: stats, orchestration, toolFlow, effectiveness, patterns, modelDelegation, errorPropagation, concurrency, complexity, compaction, cooccurrence |
Score Components (each 0, 100)
1. Completion Rate (20% weight)
From sessions_by_status:
completed / (completed + error + abandoned) × 100- Bonus for high completed-to-active ratio
- Penalty for abandoned sessions (wasted work)
2. Token Efficiency (20% weight)
From analytics tokens (baselines are pre-summed into totals):
- Cache hit rate:
total_cache_read / (total_cache_read + total_input) × 100- Above 60% = excellent, below 30% = poor
- Output concentration:
total_output / total_input, 0.3, 0.8 is balanced
3. Tool Effectiveness (20% weight)
From event_types:
- Success ratio: Count
PostToolUse/ CountPreToolUse, should be ~1.0; gap = tool failures - API error rate: Count
APIError/ total events, should be near 0 - From workflow
effectivenessdata: subagent completion rates, task success per type




