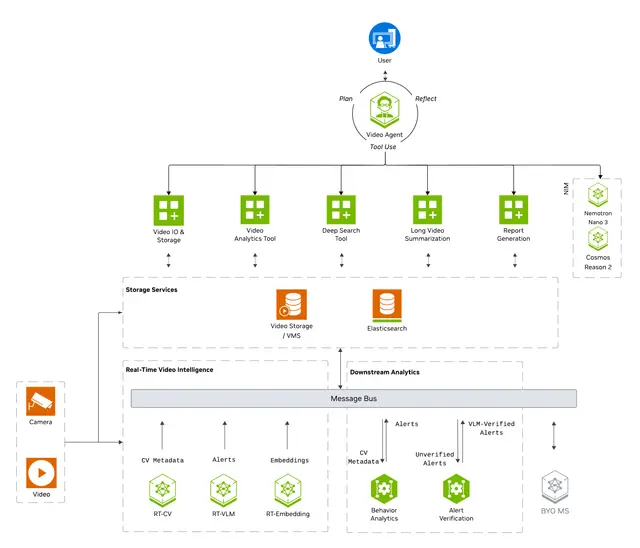
Rtvi Byom Porting
Use when adding, debugging, or validating a bring-your-own VLM in VSS RT-VLM, including...
Install
npx skills add NVIDIA-AI-Blueprints/video-search-and-summarization --skill rtvi-byom-porting -g -a claude-code -y- Category
- Testing
- Updated
- 4d ago
- License
- Apache-2.0
- Context cost
- Lightabout 1,339 tokens
- Runs scripts
- Yes, review before use
What it does
Use when adding, debugging, or validating a bring-your-own VLM in VSS RT-VLM, including a custom Hugging Face or NGC checkpoint loaded with configuration only (VLM_MODEL_TO_USE=vllm-compatible), plus adapters, plugins, shims, and model-specific runtime dependencies. Not for ordinary catalog-preset deployment of an already-wired model; use vss-deploy-dense-captioning for that.
RTVI BYOM Porting
Purpose
Port a VLM into the VSS RT-VLM service without hard-coding one checkpoint or GPU platform. Prefer configuration, then an RTVI adapter or vLLM plugin, and patch vLLM only when the supported extension points cannot express the model.
Use vss-deploy-dense-captioning for ordinary catalog-preset deployment of an
already-wired model (for example cosmos-reason3). Use this skill for a custom
or private checkpoint even when path 1 (configuration only) is enough, and when
architecture, processor, weight mapping, runtime dependencies, or request
adaptation requires repository work.
Model Contract
Before changing code, record:
- immutable model source and revision, license and access requirements;
- architecture, processor, tokenizer, quantization and context length;
- vision-token and frame-sampling assumptions;
- CUDA architecture, memory, vLLM/runtime and custom-kernel requirements.
For a private Hugging Face source, use HF_TOKEN only during authenticated
download/cache population. Never print it, embed it in MODEL_PATH, or bake it
into an image. Prove the cached model starts after the temporary credential is
removed. If remote model code is required, review it first and pair
VLM_TRUST_REMOTE_CODE=true with an exact allowlist entry. For the VSS profile,
set RTVI_VLM_MODEL_PATH_ALLOWLIST; inside the service container this becomes
RTVI_MODEL_PATH_ALLOWLIST. Likewise, the profile input
RTVI_VLM_ALLOW_UNSAFE_MODEL_CONFIG becomes
RTVI_ALLOW_UNSAFE_MODEL_CONFIG; do not enable it without reviewing the
blocked config hooks.
Integration Decision
Stop at the first path that works:





