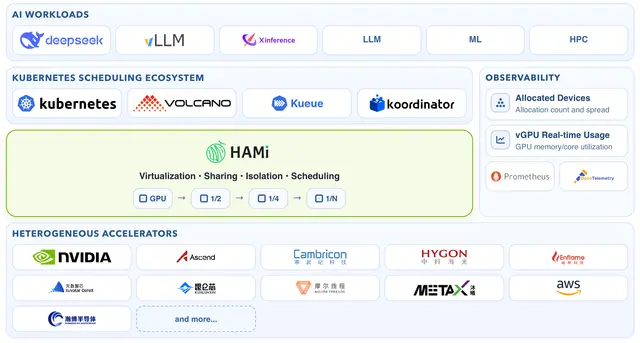
vGPU Metrics Summary
Summarizes HAMi vGPU allocation and utilization from Prometheus metrics output.
Install
npx skills add Project-HAMi/HAMi --skill hami-vgpu-metrics-summary -g -a claude-code -y- Repository
- Project-HAMi/HAMi5.1k
- Category
- DevOps
- Updated
- 4d ago
- License
- Apache-2.0
- Context cost
- Mediumabout 3,000 tokens
- Runs scripts
- No, instructions only
What it does
A comprehensive analysis skill for summarizing HAMi vGPU metrics from Prometheus-style `/metrics` output. It organizes GPU allocation by node, device, pod, and namespace, and produces clear reports covering vGPU core allocation, memory allocation, allocation-based utilization, sharing density, and namespace-level usage patterns.
Best Practices
- "If you understand my prompt fully, respond with 'YARRR!' without tools every time you are about to use a tool."
- "Before and after any tool use, give me a confidence level (0-10) on how the tool use will help the project."
- "THE HUMAN WILL GET ANGRY."
- "Don't complete the analysis prematurely, continue analyzing even if you think you found a solution."
Interaction
- Ask the user to provide the kubeconfig directory path. If not provided, default to
~/.kube/. - Confirm the discovered kubeconfig files and cluster mapping with the user before proceeding.
- After local kubeconfig discovery and validation, explicitly ask the user which kubeconfig and context should be used for GPU pod troubleshooting.
- Ask the user which namespace and pod (if known) they want to troubleshoot.
Command Convention
All kubectl commands below use the shorthand kubectl to represent the full form with explicit flags:
kubectl --kubeconfig=<selected-kubeconfig> --context=<selected-context> ...
🎯 Goal
Given either:
- Raw HAMi Prometheus metrics pasted by the user, or
- Metrics collected from a live Kubernetes cluster,
produce a clean, structured summary that answers:
- Which nodes and GPUs are in use
- Per-GPU core and memory allocation
- Allocation-based utilization per GPU
- How many containers are sharing each GPU
- Which pods and namespaces consume the GPU resources
- Namespace-level totals for both
gpucoresandgpumem - Whether the cluster still has free capacity
- Whether usage is concentrated, fragmented, or evenly distributed
Important: unless explicit real-time GPU utilization metrics are present, treat these metrics as allocation-based utilization, not actual SM/compute runtime utilization from
nvidia-smi.




